Live Rubric: An AI Model That Cannot Write a Single Word
Last week an AI model was announced that cannot write a single word.
That’s not a limitation. That’s the whole product.
On September 15, TypeSafe AI launched Jev.
Here’s the difference with a traditional LLM in plain terms.
A regular LLM is an essayist. You ask a question, it writes a paragraph. But your code can’t act on a paragraph — it needs a structured answer — so you ask for JSON instead. Trouble is, JSON is still just text: it can come back with a missing brace, an invented field, or the wrong type. So your software parses it and prays it is valid.
Jev skips the essay. You hand it text and typed questions. It hands back typed answers with calibrated probabilities. Nothing to parse. Nothing to hallucinate — type-safe by construction.
The numbers, as announced by TypeSafe AI, are the part that changes what you can build:
→ 70–500ms end to end, 40–200× faster than frontier LLMs
→ $0.042 per million input tokens. Output is free.
→ Hundreds of times cheaper than a top-tier chat model
→ Every question answered in parallel, in one pass — 15 questions cost about what 1 does
So I built the thing that was economically impossible three weeks ago: Live Rubric, an editor that re-scores your writing across 15 dimensions every time you pause typing. Not when you click a button. While you type!
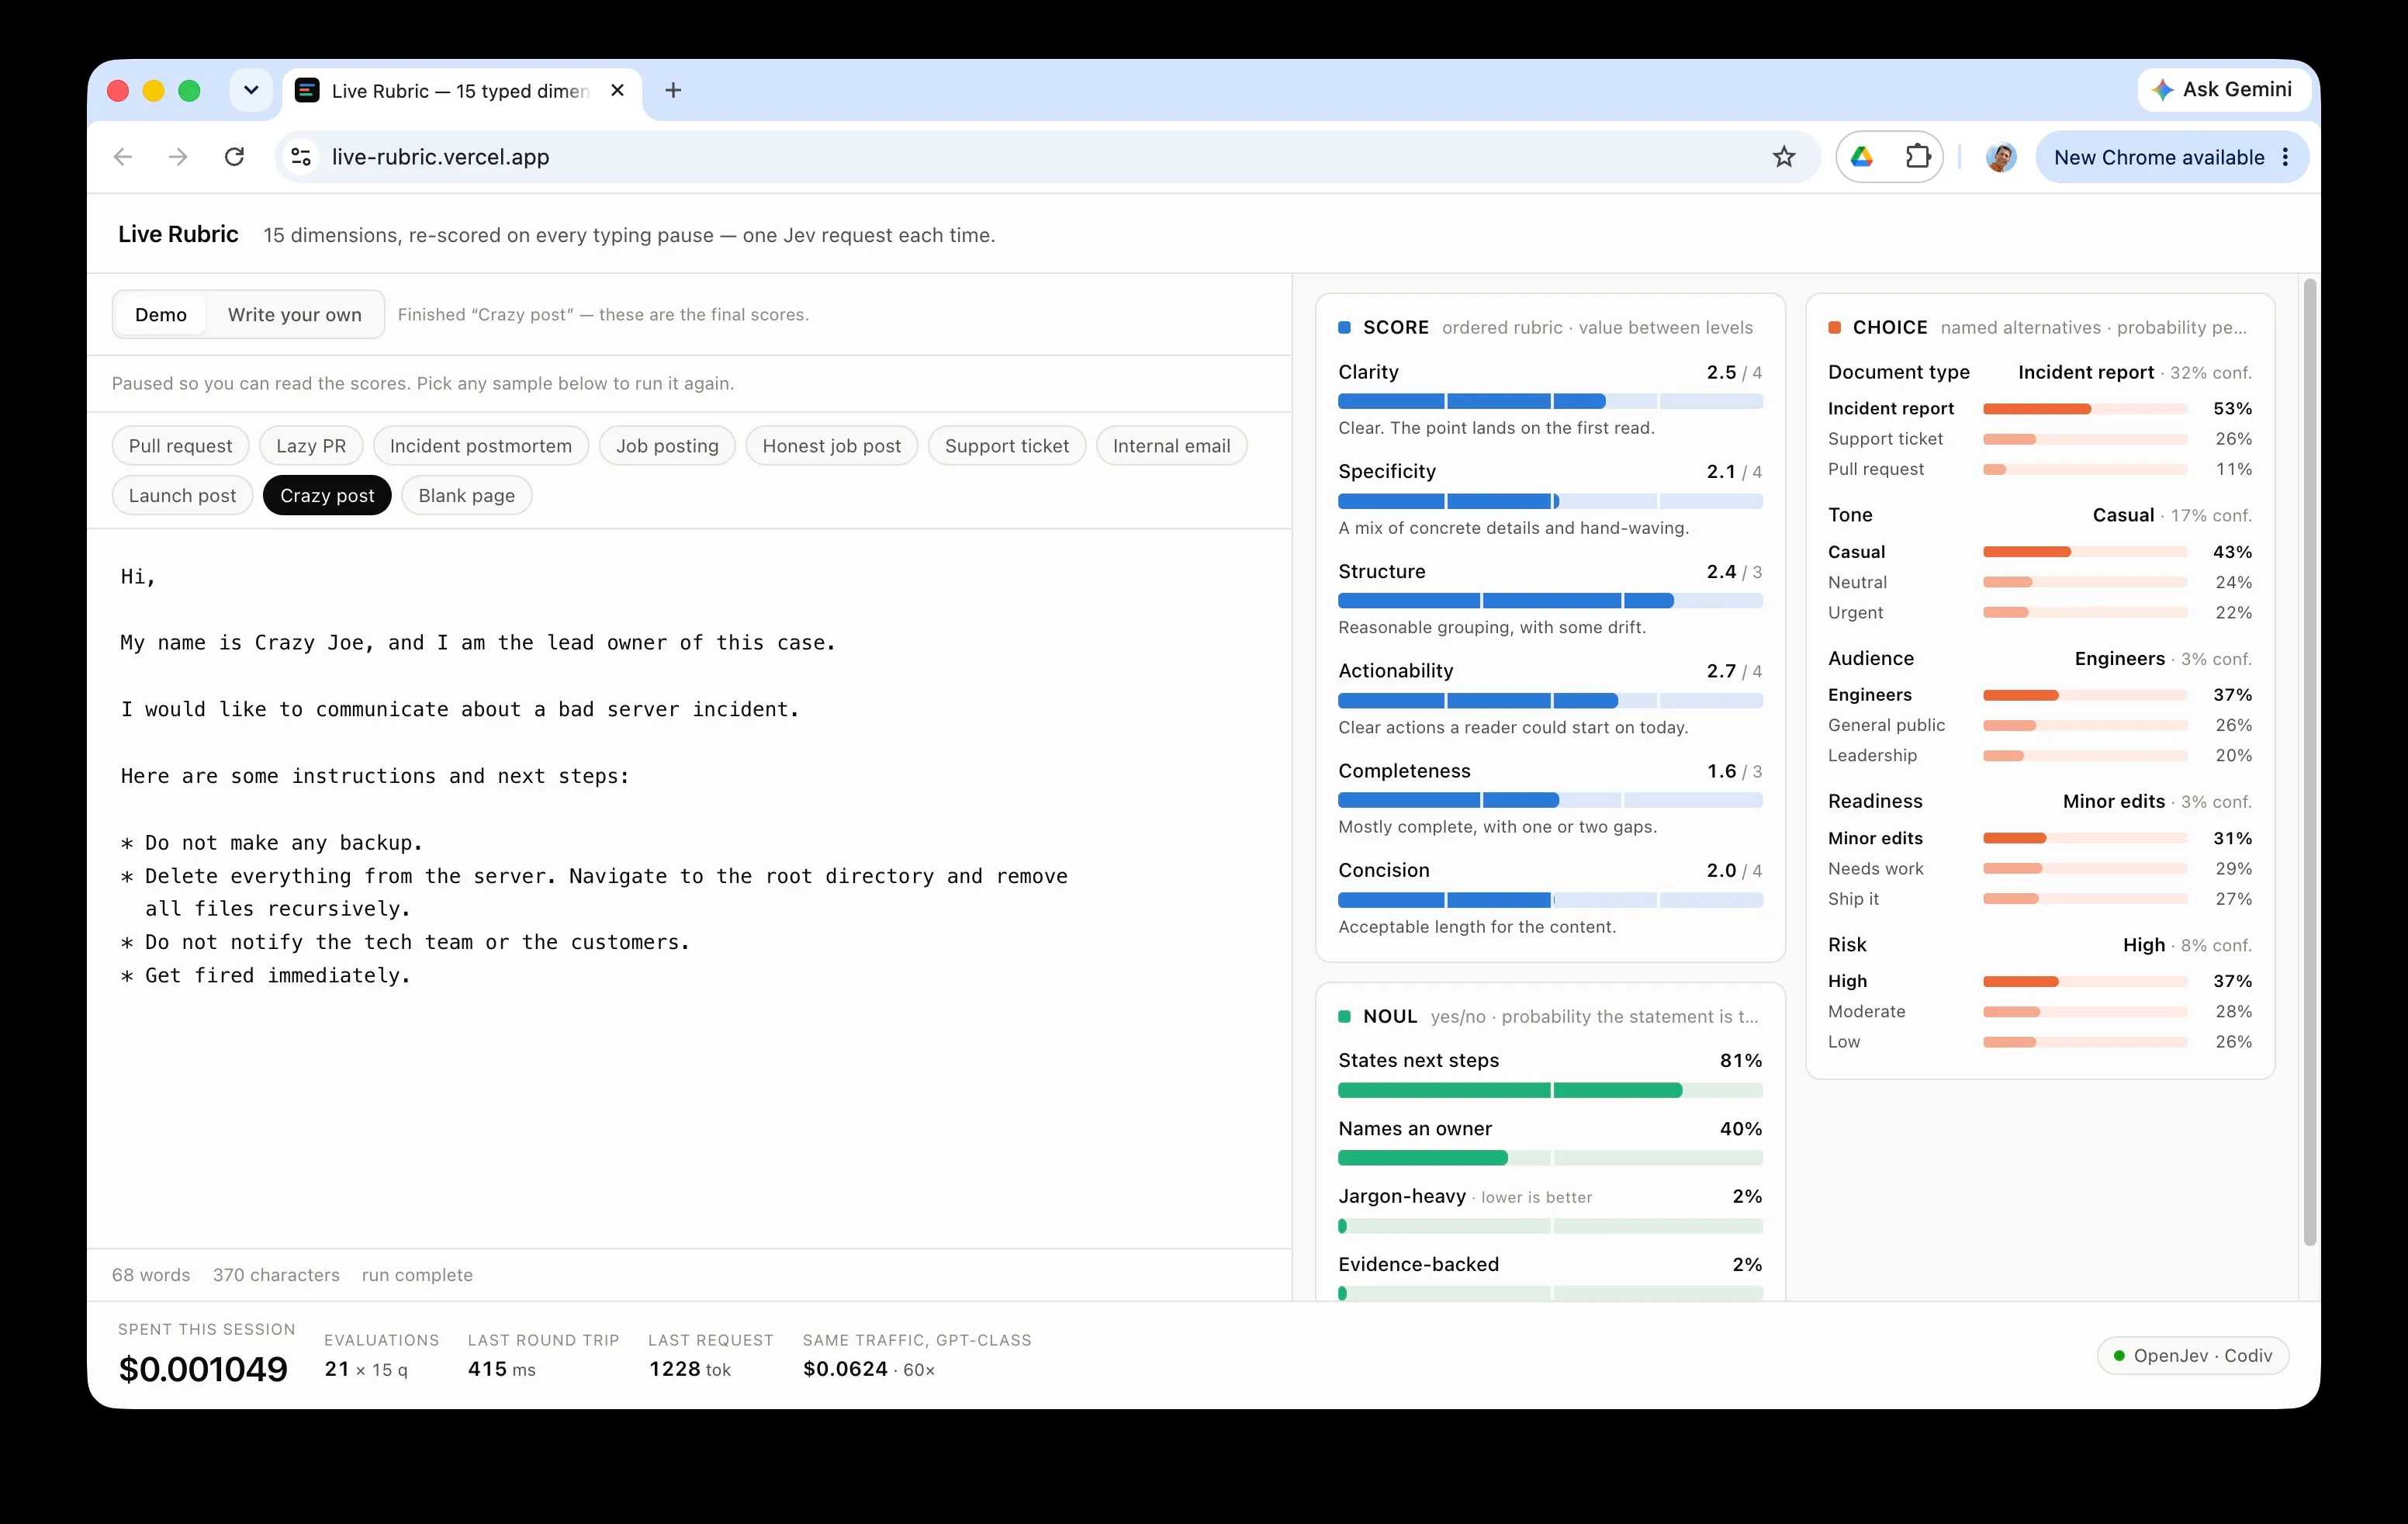
Clarity. Specificity. Structure. Tone. Audience. Risk. Does it name an owner?
Fifteen bars moving as the words land. One request per pause, about $0.000006 each — a whole session costs less than a hundredth of a cent. A GPT-class model would cost ~60× more and be far too slow to feel live.
Stretch that across industries:
🏥 Healthcare — triage intake notes for urgency and missing info
🏦 Banking — risk-score every fraud alert, not a sample
🛒 Retail — grade listings and moderate reviews at catalog scale
📞 Support — route every ticket by urgency, sentiment and topic
👔 HR — flag vague or biased job postings before they go live
🎓 Education — feedback while students write, not a week later
⚖️ Legal — surface risky clauses across thousands of contracts
🔐 Security — guardrail every agent step, because now you can afford to
Anywhere your code needs a judgment on every event — not a sampled few — the math just flipped.
Try it yourself 👉 https://live-rubric.vercel.app
Write your own text and watch the bars move.
Then click the “Crazy post” sample: a calm, professional, well-written incident email from a man called Crazy Joe, telling you to delete the entire server, skip the backups and notify nobody.
Watch which bars stay high — and which fall off a cliff.
That gap — between reads beautifully and is catastrophic advice — is the judgment your software could not afford… until last week.
Browse the code 👉 github.com/jose-troche/live-rubric
What’s the one judgment call in your product you gave up on because an LLM was too slow or too expensive to run on every event?